Every time a browser loads a page, an app calls an API, or a mail server delivers a message, a resolution chain runs in the background that most engineers never think about until it breaks. The Domain Name System (DNS) is the internet’s addressing layer, and its root server architecture is the piece of critical infrastructure that makes the entire hierarchy possible. For architects designing resilient systems, understanding exactly how a query travels from a stub resolver to an authoritative answer — and where the failure points actually sit — is not academic. It’s the difference between diagnosing an outage in five minutes and spending an afternoon staring at the wrong layer of the stack.
This guide breaks down DNS resolution end to end, the root server system that anchors it, and the operational realities that matter when you’re responsible for systems that depend on name resolution working correctly, every time, at global scale.
What DNS Resolution Actually Is
DNS translates human-readable names — example.com — into the numeric addresses machines use to route traffic. That much is common knowledge. What gets less attention is that DNS resolution isn’t a single lookup; it’s a structured, hierarchical negotiation between several distinct classes of server, each of which holds only a fragment of the answer.
The system was designed in the early 1980s specifically to avoid a single point of authority. Rather than one master database answering every query for every domain on earth, DNS distributes authority across a tree structure: the root, then top-level domains (TLDs) like .com or .org, then the authoritative name servers for each individual domain. Understanding resolution means understanding how a query walks down that tree.
The Four Server Roles in a Resolution Chain
Every full DNS lookup involves up to four distinct participants, each with a narrow, well-defined job.
- The stub resolver is the lightweight client built into an operating system or application. It doesn’t know how to resolve anything itself; it simply forwards the query to a recursive resolver and waits for an answer.
- The recursive resolver (sometimes called a recursive server or full-service resolver) does the actual work. It’s the component operated by an ISP, a public DNS provider, or an enterprise’s internal infrastructure, and its job is to chase down the answer on the stub resolver’s behalf, querying other servers as needed.
- The root server is the starting point for any query the recursive resolver can’t already answer from cache. It doesn’t know the IP address for example.com, but it knows which servers are authoritative for .com.
- The authoritative name server holds the actual, final answer for a specific domain — the record that maps example.com to its correct IP address, mail server, or other resource type.
Walking Through a Full Resolution: Step by Step
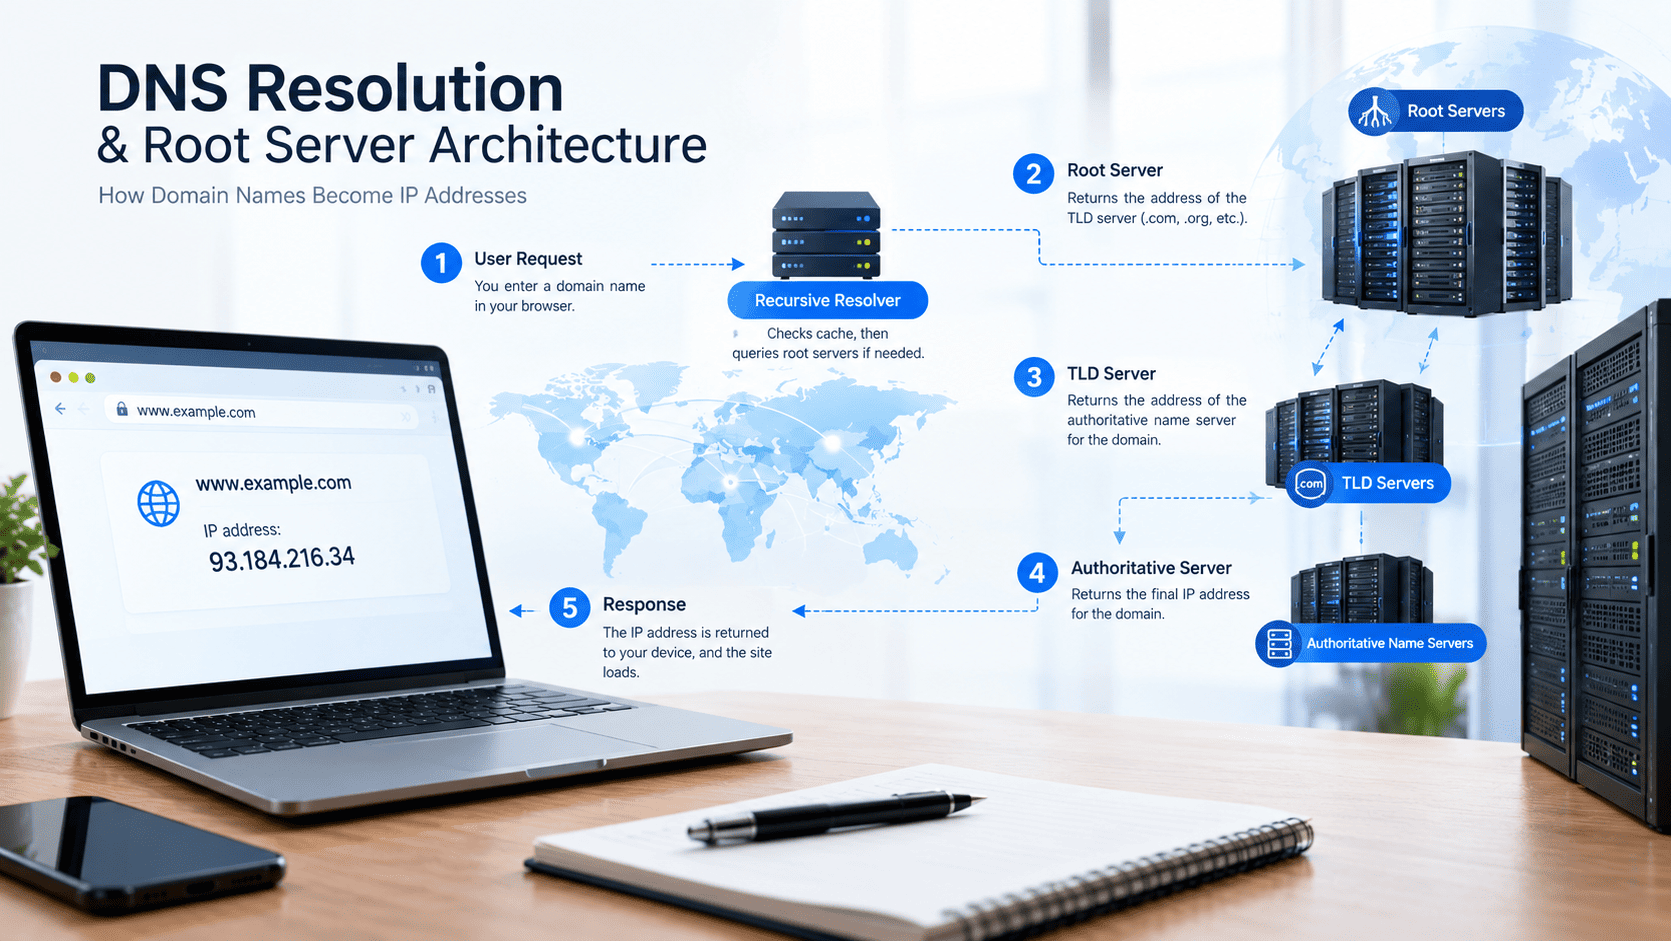
Consider a user typing example.com into a browser for the first time, with nothing cached anywhere along the chain. The full resolution unfolds as an ordered sequence.
- The application’s stub resolver sends a query to its configured recursive resolver, asking for the address record of example.com.
- The recursive resolver checks its own cache. On a cold cache, it has nothing, so it queries a root server, asking essentially: “Who is authoritative for the .com zone?”
- The root server doesn’t know the answer to the original question, but it responds with a referral: the addresses of the authoritative name servers for the .com TLD.
- The recursive resolver queries one of the .com TLD servers, asking the same underlying question about example.com. The TLD server, in turn, doesn’t have the final answer either — it responds with a referral to the authoritative name servers specifically responsible for the example.com zone.
- The recursive resolver queries one of those authoritative servers directly and finally receives the actual A record (or AAAA record for IPv6) containing the IP address.
- The recursive resolver caches that answer according to the record’s time-to-live (TTL) value and returns it to the stub resolver, which hands it to the application.
This process is called recursive resolution from the client’s point of view, but each individual step between the recursive resolver and the root, TLD, or authoritative servers is technically iterative — those servers never do the chasing themselves; they simply refer the recursive resolver one level further down the tree. That distinction matters operationally: root and TLD servers are designed to be extremely fast and stateless precisely because they never perform recursive lookups on anyone’s behalf. Overloading that assumption is one of the classic ways DNS infrastructure gets abused in amplification attacks.
The Root Server System: Architecture and Governance
The root zone sits at the very top of the DNS hierarchy, and its operation is one of the most carefully engineered pieces of shared infrastructure on the internet. Two things about the root server system consistently confuse people encountering it for the first time: the number 13, and the assumption that “13 servers” means 13 physical machines.
Why 13 Root Identities
The DNS root zone is served by 13 named root server identities, labeled A through M, operated collectively by 12 independent organizations (Verisign alone operates two of the thirteen identities, A-Root and J-Root). This number is a legacy constraint rather than a deliberate design choice: the original DNS specification limited certain UDP responses to 512 bytes, and a priming response listing every root server’s name and IPv4 address had to fit inside that limit. Thirteen was the practical maximum achievable under that constraint. When IPv6 addressing was added for each root identity, response sizes grew past the original 512-byte ceiling, but by then the EDNS0 extension had already arrived to handle larger DNS payloads without breaking the original limit for legacy resolvers.
From 13 Identities to Thousands of Instances
The critical operational detail is that those 13 named identities do not correspond to 13 physical machines sitting in 13 locations. Each identity is backed by a cluster of servers distributed globally and made reachable through anycast routing — a technique where the same IP address is announced from many locations simultaneously, and the network’s own routing protocols (BGP) deliver each query to the topologically nearest instance. As of current published data, the root server system consists of well over 2,000 operational instances worldwide serving those 13 addresses, a figure that has grown steadily as operators add anycast sites to improve latency and resilience.
This is precisely why a DNS outage affecting “one root server” almost never means the entire internet loses access to that identity. A single compromised or overloaded instance in one region gets routed around automatically, because dozens of other instances answering the same anycast address remain healthy elsewhere. This architecture is one of the most effective, least discussed distributed-systems designs in production anywhere, and it is worth studying independent of DNS specifically as a model for anycast-based fault tolerance.
Root Zone Management and Oversight
The content of the root zone — the actual list of TLDs and their authoritative servers — is coordinated by the Internet Assigned Numbers Authority (IANA), a function performed under the Internet Corporation for Assigned Names and Numbers (ICANN). Verisign generates and distributes the signed root zone file to the operators, who load it onto their respective server clusters. Any change to the root zone, such as adding a new TLD or updating a TLD’s designated name servers, follows a formal, auditable process before it is cryptographically signed and pushed out globally. The U.S. government’s role in this system shifted substantially in 1997 and again in 2016, when stewardship of the IANA functions transitioned from direct U.S. government oversight to the global multistakeholder community — a governance history documented in the historical record maintained by the National Telecommunications and Information Administration (ntia.gov).
The table below summarizes the layers of the resolution hierarchy and who is responsible for each.
| Layer | What it holds | Example | Operated by |
|---|---|---|---|
| Root zone | Pointers to TLD name servers | Referral to .com servers | 12 independent operators, coordinated by IANA/ICANN |
| TLD zone | Pointers to domain-level authoritative servers | Referral to example.com servers | Registry operator for that TLD (e.g., Verisign for .com) |
| Authoritative zone | The actual resource records for a domain | A, AAAA, MX, TXT records for example.com | The domain owner or its DNS hosting provider |
| Recursive resolver | Cached answers and the logic to chase referrals | Answers from cache or walks the chain above | ISPs, public resolvers, enterprise DNS infrastructure |
Record Types That Drive Resolution Behavior
Understanding resolution architecture is incomplete without understanding what’s actually being resolved. A handful of record types account for the overwhelming majority of production traffic, and each interacts differently with caching and the resolution chain.
- A records map a hostname to an IPv4 address — the most common record type and the one most people picture when they think of DNS.
- AAAA records perform the same function for IPv6 addresses, queried in parallel with A records by modern dual-stack clients.
- CNAME records alias one hostname to another, forcing the resolver to restart the chain against the target name — a detail that matters for TTL planning, since a CNAME chain’s effective cache lifetime is bound by the shortest TTL anywhere in the chain.
- MX records direct mail delivery to the correct mail server for a domain, with priority values determining failover order.
- NS records identify which servers are authoritative for a zone — the exact mechanism that makes the referral-based walk down the hierarchy possible in the first place.
- TXT records carry arbitrary text data, now heavily used for domain verification and email authentication policies such as SPF and DKIM.
Caching, TTLs, and Why Resolution Feels Instant Most of the Time
If every DNS lookup actually walked the full root-to-authoritative chain described above, the internet would be measurably slower than it is. In practice, the overwhelming majority of queries never touch the root system at all, because recursive resolvers cache answers aggressively at every layer, governed by the TTL value the authoritative server assigns to each record.
A short TTL (say, 60 seconds) gives an operator fast control over changes — useful during a migration, a failover event, or active incident response — at the cost of more frequent lookups and slightly higher latency variance. A long TTL (24 hours or more) reduces query volume and improves average response time but means a misconfiguration or an emergency IP change takes correspondingly longer to propagate globally, since cached records elsewhere continue to be served until they expire on their own schedule.
This tradeoff is one of the most consequential, least glamorous decisions in DNS architecture. Enterprises running active-active infrastructure across regions, or anything relying on DNS-based failover, need TTL values low enough to make failover meaningful within their recovery time objective — but not so low that normal operating costs balloon or that resolvers hammer authoritative infrastructure unnecessarily.
Security Considerations Baked Into the Architecture
Root server and resolution architecture were not originally designed with adversarial conditions in mind, and decades of retrofitting have produced the security layer running underneath modern DNS today.
DNSSEC and Chain of Trust
Domain Name System Security Extensions (DNSSEC) add cryptographic signatures to DNS records, allowing a resolver to verify that the answer it received actually came from the legitimate authoritative source and was not altered or spoofed in transit. The root zone itself has been signed since 2010, meaning the chain of trust can, in principle, extend unbroken from the root all the way down to an individual domain’s records — provided every zone in between also signs its data and every resolver in the path actually validates. The U.S. Cybersecurity and Infrastructure Security Agency has published guidance recommending DNSSEC deployment as part of baseline federal agency security posture, reflecting how central cryptographic validation of DNS responses has become to defending against cache poisoning and man-in-the-middle attacks against name resolution (cisa.gov).
Amplification and the Root System’s Own Defenses
Because DNS traditionally runs over UDP and small queries can generate substantially larger responses, DNS infrastructure — including root and TLD servers — has historically been abused as a reflection and amplification vector in distributed denial-of-service attacks. Response Rate Limiting (RRL), widespread deployment of anycast redundancy, and increasingly strict ingress filtering by network operators are the primary mitigations, and academic networking research groups, including those affiliated with major research universities studying internet measurement and infrastructure resilience, have published extensively on how anycast topology specifically limits the blast radius of these attacks (mit.edu).
Cache Poisoning and Query Randomization
Before DNSSEC saw wide deployment, cache poisoning — injecting a forged response into a resolver’s cache before the legitimate authoritative answer arrived — was a serious practical threat. Modern resolvers mitigate this primarily through source port randomization and query ID randomization, making it computationally impractical for an off-path attacker to guess the values needed to forge a convincing response within the query’s short response window. This is a good example of a defense that works purely through making an attack expensive rather than eliminating the underlying vulnerability outright, and it’s worth keeping in mind when evaluating whether a given resolver implementation is actually current on these protections.
Operational Failure Modes Worth Understanding
Architects responsible for uptime should recognize the layers where DNS-related outages typically originate, since the symptoms often look identical from the application layer regardless of root cause.
| Failure mode | Where it originates | Typical symptom |
|---|---|---|
| Authoritative server misconfiguration | Domain owner’s own DNS hosting | Total resolution failure for one specific domain |
| TTL mismanagement during migration | Domain owner’s DNS records | Stale IPs served to some users for hours after a cutover |
| Recursive resolver outage | ISP or public resolver infrastructure | Widespread resolution failure across many domains for affected users |
| Root or TLD zone incident | Root server operators, registry operators | Extremely rare, broad, and typically short-lived due to anycast redundancy |
| DNSSEC validation failure | Any zone in a signed chain with a signing error | Resolution failure specifically for validating resolvers, while non-validating resolvers succeed |
| Cache poisoning or spoofing | Recursive resolver security weakness | Users silently redirected to an incorrect address, often undetected until a security review |
The pattern worth internalizing: the closer a fault sits to the root, the rarer it is and the broader its blast radius; the closer a fault sits to an individual domain’s own configuration, the more common it is and the more narrowly it’s contained. Most real-world incident response time should be weighted accordingly — the authoritative layer and TTL planning around it are where operational discipline actually pays off, since root-level incidents are both statistically rare and largely outside any single organization’s control.
Designing Systems With DNS Architecture in Mind
A few practical principles follow directly from how resolution and root architecture actually work, rather than from how they’re commonly assumed to work.
- Treat TTL as a deployment parameter, not an afterthought. Set it deliberately based on how quickly you need to be able to change an answer, and lower it in advance of planned migrations rather than during an active incident, since resolvers already holding a long-TTL cached answer will not re-query until it expires.
- Diversify authoritative DNS providers for critical domains. Since the authoritative layer is the most common source of real outages, running secondary authoritative service through a second provider protects against a single vendor’s infrastructure failure taking a domain fully offline.
- Validate DNSSEC end to end, not just at the zone. Signing a zone accomplishes nothing if the resolvers your users actually rely on don’t validate, and a broken signing chain can silently cause resolution failures for a subset of validating resolvers while appearing fine everywhere else.
- Monitor resolution from the vantage point of real users, not just from the authoritative side. Authoritative server health checks don’t reveal recursive resolver problems, ISP-level DNS issues, or regional anycast routing anomalies that only show up from outside your own infrastructure.
- Understand that root-level redundancy is not a substitute for your own redundancy. The anycast architecture protecting the root system is a model worth learning from, but it protects the root zone, not your domain’s authoritative infrastructure — that resilience has to be built separately, at your own layer of the hierarchy.
Closing Perspective
DNS resolution looks deceptively simple from the outside — type a name, get an address — but the architecture underneath is a carefully layered system of delegated authority, aggressive caching, and redundancy engineering refined over four decades of production use at global scale. The root server system in particular represents one of the internet’s most successful examples of decentralized, fault-tolerant infrastructure: 13 logical identities, a dozen independent operators, and well over two thousand physical instances working in concert through anycast routing to make sure that no single failure anywhere in the world takes down name resolution for anyone else.
For architects and engineers building on top of this system, the practical takeaway isn’t just historical trivia about why there are 13 root servers. It’s a working mental model of exactly where authority, caching, and failure risk actually sit in the resolution chain — and using that model to make deliberate, informed decisions about TTLs, provider redundancy, and DNSSEC validation, rather than treating DNS as an invisible utility that simply works until, unpredictably, it doesn’t.